Showing posts with label ASIC. Show all posts

Tuesday, 6 November 2018

Automatic configuration through uvm_config_db

UVM has an internal database table in which we can store values (of any data type including user defined data type) with unique name and can be retrieved later by some other testbench component.
There are two interface through which we can access configuration database.
1) uvm_resource_db, 2) uvm_config_db

Uvm_config_db is a great way to pass different resources (variable/object/virtual interface) within UVM testbench component hierarchy.

The uvm_config_db class provides a convenience interface on top of the uvm_resource_db to simplify the basic interface that is used for configuring uvm_component instances.

Let’s go through basic example:
-------------------------------------------------------------------------
-------------------------------------------------------------------------

UVM provides automatic configuration of resources (variable/object etc…) which are registered in the respective component (which is extended from uvm_component) by calling apply_config_settings method.
Any component which is extended from uvm_component should call super.build_phase(phase) to execute apply_config_settings method.
Let's go through basic example of automatic configuration.
-------------------------------------------------------------------------
-------------------------------------------------------------------------

But,
This is not recommended approach as it introduces extremely poor simulation performance and big confusion on what kind of field/resource it supports and does not supports.

Some of the types get automatically configured and while some are not.

Let’s go through one more example of automatic configuration,
-------------------------------------------------------------------------
-------------------------------------------------------------------------

Observation:
1)      If you set any object which is extended from uvm_object and set it into config_db using extended type it won't get automatically configured (obj2).
2)      If you set extended object into config_db using uvm_object as type then it will get automatically configured (obj1).
3)      Unpack array will not get automatically configured (ary_int).
4)      If resource (variable/object etc) is not registered in respective class using `uvm_field_* macro then it won't get automatically configured (idx1).
5)      Virtual interface won't get automatically configured as we can't register it using `uvm_field_* macro.
6)      If you set any vector (let’s say bit [47:0]) in config_db using uvm_config_db#(int)::set then it will get automatically configured. Even though width of int is 32 bit but still 48 bits will get automatically configured (idx2).
7)      But if you set same vector (bit [47:0]) in config_db using uvm_config_db#(bit[47:0])::set then it won't get automatically configured (idx22).


If you want to pass Unpack array using uvm_config_db then you can set it directly using for loop as done in above example. But this is not efficient approach, instead of that create a class (extended from uvm_object) that includes unpack arrays and then do set/get of that class using uvm_config_db.

Reference:
1) https://verificationacademy.com/forums/uvm/uvmconfigdb-usage-big-confusion

Sunday, 28 January 2018

Automatic/Static Variables and Function/Task with Automatic Lifetime in SystemVerilog

Before going into static and automatic variable let’s first go through 2 important terminology and then will go through automatic and static.

Scope:
Scope is the region or section of code where a variable can be accessed.
Variables declared inside a module, interface, program, or checker, but outside a task, process, or function, are local in scope.

Lifetime:
Lifetime is the time duration where an object/variable is in a valid state.
Variables declared outside a module, program, interface, checker, task, or function are local to the
compilation unit and have a static lifetime (exist for the whole simulation).
Variables declared inside a static task, function, or block are local in scope and default to a static lifetime.

Specific variables within a static task, function, or block can be explicitly declared as automatic. Such
variables have the lifetime of the call or block and are initialized on each entry to the call or block.
---------------------------------------------------------------------
---------------------------------------------------------------------
Result:
---------------------------------------------------------------------
---------------------------------------------------------------------


Automatic Function/Task (Function/Task with Automatic Lifetime):
In Verilog default lifetime of all the task/function is static.
Tasks and functions may be declared as automatic. Variables declared in an automatic task, function, or block are local in scope, default to the lifetime of the call or block, and are initialized on each entry to the call or block.

In other word, Automatic task/function variables cannot be accessed by hierarchical references. Automatic variables are automatically destroyed once the scope (task, function, block) in which they are created ends and regenerated when again enters into scope (task, function, block).
---------------------------------------------------------------------
---------------------------------------------------------------------


Class methods has Automatic lifetime by default:
Because of backward compatibility reason, SystemVerilog could not change the default lifetime qualifier to ‘automatic’ but since class methods were new, it changed the lifetime of all methods to be automatic.
---------------------------------------------------------------------
---------------------------------------------------------------------


The keyword ‘static’ is overloaded. There is a semantic difference between the meaning of ‘static’ used to the left of a function/task keyword and ‘static’ used to the right of the function/task keyword.

When used to the left of the function or task, ‘static’ is a class qualifier and has the same as on any static method in C++/Java. It is a method of the class type, not of an instance of a class object. Other class qualifiers are ‘local’ and ‘protected’ and along with ‘static’ are only allowed in front of methods of a class. There is no corresponding ‘automatic’ class qualifier.

When used to the right of a function or task, ‘static’ is a lifetime qualifier, with ‘automatic’ being the corresponding qualifier.

For more details refer this link.

Friday, 26 January 2018

`define macro usage in SystemVerilog

It's not possible to use a `define macro within a string literal. According to the SystemVerilog LRM: Macro substitution and argument substitution shall not occur within string literals
Let’s go through below example to understand it in detail,
 ---------------------------------------------------------------------------
 ---------------------------------------------------------------------------

However a string literal can be constructed by using a macro that takes an argument and including the quotes in the macro by using `".
According to SystemVerilog LRM: An `" overrides the usual lexical meaning of " and indicates that the expansion shall include the quotation mark, substitution of actual arguments, and expansions of embedded macros. This allows string literals to be constructed from macro arguments.
 ---------------------------------------------------------------------------
 ---------------------------------------------------------------------------

Now what if you want to add double quotes in string which is constructed using macro. SystemVerilog provides support for that.
A `\`" indicates that the expansion should include the escape sequence \".
Let’s go through example to see how it works,
 ---------------------------------------------------------------------------
 ---------------------------------------------------------------------------

 SystemVerilog LRM also provides support to construct identifier from arguments using ``.
There are three places where we can substitute argument to construct identifier
1) Substitute argument in between something (neither at the end nor at the beginning of the identifier)
2) Prepend argument (at the beginning of the identifier)
2) Append argument (at the end of the identifier)
 ---------------------------------------------------------------------------
 ---------------------------------------------------------------------------

Reference:
1) SystemVerilog 2012 LRM

Weighted Distributions in SystemVerilog

In constrain random verification, it may take a long time for a particular corner case to be generated. Sometime even after running test-case for N number of time corner case may not be generated and you may see holes in functional coverage. To resolve this you can use a weighted distribution to drive stimulus in particular direction.

The dist keyword in systemverilog allows you to create weighted distributions so that some values are chosen more often than others. There are 2 different kind of distribution operators available in systemverilog.
The := operator assigns the specified weight to the item or, if the item is a range, to every value in the range. 
The :/ operator assigns the specified weight to the item or, if the item is a range, to the range as a whole. If there are n values in the range, the weight of each value is range_weight / n.

Limitation:
dist expressions cannot appear in other expressions.
dist operation shall not be applied to randc variables.

Let's go through below example to understand how it works,
----------------------------------------------------------------------------
----------------------------------------------------------------------------

Reference:
1) SystemVerilog LRM 2012
2) SystemVerilog for Verification 3rd edition by Chris Spear

Wednesday, 8 November 2017

Timeunit and Timeprecision in SystemVerilog

Within a design element, such as a module, program or interface, the time precision specifies how delay values are rounded before being used in simulation.

The time precision is relative to the time units. If the precision is the same as the time units, then delay values are rounded off to whole numbers (integers). If the precision is one order of magnitude smaller than the time units, then delay values are rounded off to one decimal place.

For example, if the time unit specified is 1ns and the precision is 100ps, then delay values are rounded off to one decimal place (100ps is equivalent to 0.1ns). Thus, a delay of 2.75ns would be rounded off to 2.8ns.

The time unit and time precision can be specified in the following two ways:
— Using the compiler directive `timescale
— Using the keywords timeunit and timeprecision

Here in this post, we will go in details of second way (timeunit and timeprecision).

The time precision may also be declared using an optional second argument to the timeunit keyword using the slash separator. For example:

------------------------------------------------------------------------------
------------------------------------------------------------------------------

Defining the timeunit and timeprecision constructs within the design element removes the file order dependency problems with compiler directives.

There shall be at most one time-unit and one time-precision for any module, program, package, or interface definition or in any compilation-unit scope. This shall define a time scope.

The timeunit and timeprecision declarations shall precede any other items in the current time scope. i.e. timeunit and timeprecision shall be declared either inside module, program, package, interface or after any item in any compilation-unit scope.

The timeunit and timeprecision declarations can be repeated as later items, but must match the previous declaration within the current time scope.

If a timeunit is not specified within a module, program, package, or interface definition, then the time unit shall be determined using the following rules of precedence:
  1. If the module or interface definition is nested, then the time unit shall be inherited from the enclosing module or interface (programs and packages cannot be nested).
  2. Else, if a `timescale directive has been previously specified (within the compilation unit), then the time unit shall be set to the units of the last `timescale directive.
  3. Else, if the compilation-unit scope specifies a time unit (outside all other declarations), then the time unit shall be set to the time units of the compilation unit.
  4. Else, the default time unit shall be used.


The global time precision, also called the simulation time unit, is the minimum of,
  • All the timeprecision statements,
  • All the time precision arguments to timeunit declarations, and
  • The smallest time precision argument of all the `timescale compiler directives in the design.

Let's go through one example,
------------------------------------------------------------------------------
------------------------------------------------------------------------------

Reference:
1) SystemVerilog LRM (1800-2012)

Tuesday, 26 September 2017

Array Manipulation Methods in SystemVerilog with example

SV provides build in methods to facilitate searching from array, array ordering and reduction.

Array locator methods:

Array locator methods operate on any unpacked array, including queues, but their return type is a queue.

Element locator methods (with clause is mandatory):
find() returns all the elements satisfying the given expression.
find_first() returns the first element satisfying the given expression.
find_last() returns the last element satisfying the given expression.

Index locator methods (with clause is mandatory):
find_index() returns the indices of all the elements satisfying the given expression.
find_first_index() returns the index of the first element satisfying the given expression.
find_last_index() returns the index of the last element satisfying the given expression.

Index locator methods return a queue of int for all arrays except associative arrays, which return a queue of the same type as the associative index type.
arrays that specify a wildcard index type shall not be allowed.

If no elements satisfy the given expression or the array is empty (in the case of a queue or dynamic array), then an empty queue is returned.

Index locator methods return a queue with the indices of all items that satisfy the expression.

The optional expression specified by the with clause shall evaluate to a Boolean value.

Let's go through below example,
---------------------------------------------------------------------
---------------------------------------------------------------------

Element locator methods (with clause is optional):
min() returns the element with the minimum value or whose expression evaluates to a minimum.
max() returns the element with the maximum value or whose expression evaluates to a maximum.
unique() returns all elements with unique values or whose expression evaluates to a unique value.
unique_index() returns the indices of all elements with unique values or whose expression evaluates to a unique value.

Let's go through below example,
---------------------------------------------------------------------
---------------------------------------------------------------------

Array reduction methods:


Array reduction methods may be applied to any unpacked array of integral values to reduce the array to a single value

sum() returns the sum of all the array elements or, if a with clause is specified, returns the sum of the values yielded by evaluating the expression for each array element.

product() returns the product of all the array elements or, if a with clause is specified, returns the product of the values yielded by evaluating the expression for each array element.

and() returns the bitwise AND ( & ) of all the array elements or, if a with clause is specified, returns the bitwise AND of the values yielded by evaluating the expression for each array element.

or() returns the bitwise OR ( | ) of all the array elements or, if a with clause is specified, returns the bitwise OR of the values yielded by evaluating the expression for each array element.

xor() returns the bitwise XOR ( ^ ) of all the array elements or, if a with clause is specified, returns the bitwise XOR of the values yielded by evaluating the expression for each array element.

Let's go through below example,
---------------------------------------------------------------------
---------------------------------------------------------------------

Array ordering methods:

Array ordering methods reorder the elements of any unpacked array (fixed or dynamically sized) except for associative arrays.

reverse() reverses the order of the elements in the array. Specifying a with clause shall be a compiler error.

sort() sorts the array in ascending order, optionally using the expression in the with clause.

rsort() sorts the array in descending order, optionally using the expression in the with clause.

shuffle() randomizes the order of the elements in the array. Specifying a with clause shall be a compiler error.

Let's go through below example,
---------------------------------------------------------------------
---------------------------------------------------------------------


Now let's see couple of practical examples, let's say we want to find number of 1s from bit array or bit queue or we want to find out number of non-zero elements in any array or queue.
---------------------------------------------------------------------
---------------------------------------------------------------------

Thursday, 23 March 2017

Automatic raise/drop objection with UVM-1.2

Variable uvm_sequence_base::starting_phase is deprecated and replaced by two new methods set_starting_phase and get_starting_phase, which prevent starting_phase from being modified in the middle of a phase. This change is not backward-compatible with UVM 1.1, though variable starting_phase, although deprecated, has not yet been removed from the base class library.

New method uvm_sequence_base::set_automatic_phase_objection causes raise_objection and drop_objection to be called automatically around a sequence, avoiding the need to call raise/drop_objection manually in one common situation.

Lets understand it trough below mentioned example.
------------------------------------------------

------------------------------------------------


Ref:
1) https://www.doulos.com/knowhow/sysverilog/uvm/uvm-1.2/

Tuesday, 21 February 2017

Lock and Grab of sequencer in UVM

There are a number of modelling scenarios where one sequence needs to have exclusive access to a driver via a sequencer. One example of this type of scenario is a sequence which is responding to an interrupt.
In order to accommodate this requirement, the uvm_sequencer provides 2 types of mechanism called lock()-unlock() and grab()-ungrab().

If sequencer is doing some sequence and based on some external events if user wants sequencer to pause the current sequence, he/she can grab/lock sequencer and start another sequence. Once the started sequence finishes sequencer can resume the normal operation, upon ungrab/unlock.
This mechanism is generally used to mimic CPU behavior, where CPU is doing a normal bus operation and when interrupt comes, CPU needs to suspend the normal operation and start interrupt handling. Once interrupt handling is over, CPU should resume the normal operation from where it was suspended.

A lock might be used to model a prioritized interrupt and a grab might be used to model a non-mask able interrupt (NMI).
The lock() and grab() calls have antidote calls to release a lock and these are unlock() and ungrab().

Lock()
1) A lock() request is put in back of the arbitration queue . A lock request will be arbitrated the same as any other request.
2) A lock is granted after all earlier requests are completed and no other locks or grabs are blocking this sequence.
3) A lock() is blocking task and when access is granted, it will unblock.
4) If no argument is supplied, then current default sequencer is chosen.

Grab()
1) A grab() request is put in front of the arbitration queue. A grab() request will be arbitrated before any other requests.
2) A grab() is granted when no other grabs or locks are blocking this sequence. (The only thing that stops a sequence from grabbing a sequencer is a pre-existing lock() or grab() condition.)
3) A grab() is blocking task and when access is granted, it will unblock.
4) If no argument is supplied, then current default sequencer is chosen.

Unlock()
The unlock sequencer function is called from within a sequence to give up its lock or grab. A locking sequence must call unlock before completion; otherwise the sequencer will remain locked.

Ungrab()
An alias of function unlock().


What happens if 2 sequences try to grab or lock the same sequencer?
The most recent grab goes to the front of the queue; the most recent lock goes to the back of the queue.

Priority in lock() and grab().
The most recent grab comes first, then the previous grab... then the oldest lock, then the most recent lock.

Let’s go through basic example of lock() and grab()
1) Lock
---------------------------------------------
---------------------------------------------

2) Grab
---------------------------------------------
---------------------------------------------
From output of above two examples, we can see the difference between lock() and grab() as mentioned above.


When a hierarchical sequence locks/grab a sequencer, then its child sequences will have access to the sequencer.
If one of the child sequences issues a lock/grab, then the parent sequence will not be able to start any parallel sequences or send any sequence_items until the child sequence has unlocked.
---------------------------------------------
---------------------------------------------


A locking or grabbing sequence must always unlock before it completes,
---------------------------------------------
---------------------------------------------

Now let’s go through one example where 2 virtual sequences are running in parallel and one virtual sequence put lock/grab on agent’s sequencer.

---------------------------------------------
---------------------------------------------

Thursday, 16 February 2017

Difference between @event and wait(event.triggered) in SystemVerilog and usage of non-blocking event

The event data type provides a handle to a synchronization object.

There are two ways through which we can wait for particular event to be triggered.
So let's understand what is the exact difference between those 2 ways.

-----------------------------------------------

-----------------------------------------------

An event trigger ->e is an instantaneous event. The event waiting process @ shall execute before the triggering process -> executes. If the trigger executes first, then the waiting process remains blocked.

The triggered event property evaluates to true (1'b1) if the given event has been triggered in the current time step and false (1'b0) otherwise.
Now you no longer have to worry which came first, the triggering process –> or the waiting process @ statement. But you still have to execute the waiting process @ in the current time slot to catch the event.

Let’s see the behavior with examples,
-----------------------------------------------

-----------------------------------------------

-----------------------------------------------

-----------------------------------------------

The other workaround is to use nonblocking event

Non-blocking event ->>
Nonblocking events are triggered using the ->> operator.

The effect of the ->> operator is that the statement executes without blocking, and it creates a nonblocking assign update event in the time in which the delay control expires or the event control occurs. The effect of this update event shall be to trigger the referenced event in the nonblocking assignment region of the simulation cycle.

-----------------------------------------------
-----------------------------------------------

Wednesday, 23 November 2016

Kill process in SystemVerilog using "disable fork" and "disable LABEL"

Most of us, have faced these some issues at least one time in our SystemVerilog programming while using "disable fork" and "disable LABEL".

Let's first go through below example,
------------------------------------------------------------------------------

------------------------------------------------------------------------------

As shown in above example, "Process:1" is running continuously. Two different processes, "Process:2" and "Process:3" should run in parallel and any of two processes is completed, other process shall stop its execution due to join_any statement.

While simulating above code, you may face that when the disable fork is executed, "Process:1" also stop it's execution. So, to avoid this kind of situation, it's better to use "disable LABEL" statement.
------------------------------------------------------------------------------

------------------------------------------------------------------------------

Above code works fine with a single instance of that class. But when there are multiple instances of the same class in the test-bench and all the instances are executing their threads simultaneously then the simulation will stop after executing "disable LABEL" statement of any instance.
------------------------------------------------------------------------------

------------------------------------------------------------------------------

There are two ways to handle these kind of situations.
1) Limiting scope of "disable fork" by adding one extra hierarchy of fork...join.
2) Using "process" class of SystemVerilog

Let's see both ways through example,
------------------------------------------------------------------------------

------------------------------------------------------------------------------


------------------------------------------------------------------------------

------------------------------------------------------------------------------

Wait for more than one processes of fork...join_none to complete

In our project some time we want to wait for more than one process which is invoked from fork...join_none or join_any before proceeding further.

How to achieve this using SystemVerilog constructs, that we will understand through an example.

Let's go through below code,
-------------------------------------------------------------------------------------

-------------------------------------------------------------------------------------

In above code, class abc is having one method named multiple_process().
In API, within fork...join_none 4 process are invoked in parallel.
Each process puts one key into semaphore just before it's completed (Initially semaphore doesn't have any key).

After fork...join_none, I am waiting for semaphore to get at least two key ().

Friday, 26 August 2016

Callback vs Factory in UVM

Callbacks and factory address different areas of re-usability.

Callback: Add functionality to existing logic.

Factory: Change the existing component before build, keeps environment same.

Although the callback and factory can be interchangeably used to address the same problem. Depending on the need and demand, a wise decision should be made while adopting either of the techniques as they have their own merits and demerits.


Wednesday, 22 June 2016

Strength in Verilog

Strengths can be used to resolve which value should appear on a net or gate output.
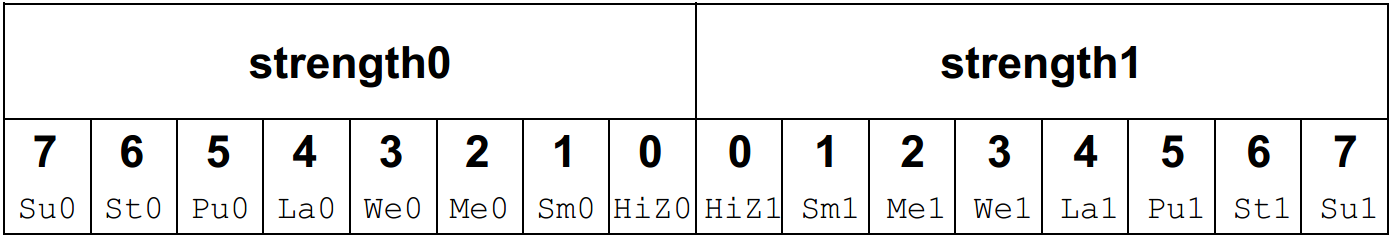
A strength specification shall have the following two components:
• The strength of the 0 portion of the net value, called strength0, designated as one of the following:
supply0 strong0 pull0 weak0 highz0
• The strength of the 1 portion of the net value, called strength1, designated as one of the following:
supply1 strong1 pull1 weak1 highz1
The combinations (highz0, highz1) and (highz1, highz0) shall be considered illegal.

There are four driving strengths: supply strong pull weak
Signals with driving strengths shall propagate from gate outputs and continuous assignment outputs.

There are three charge storage strengths: large medium small
Signals with the charge storage strengths shall originate in the trireg net type.

It is possible to think of the strengths of signals as locations on the scale

When signals combine, their strengths and values shall determine the strength and value of the resulting signal in accordance with the principle.

1) If two or more drivers drive a signal with different strength then it will have the value of the strongest driver
Ex-1:
buf (strong1, weak0) g1 (y, a);
buf (pull1, supply0) g2 (y, b);
• If a = 0 and b = 0 then y will be 0 with supply strength because both gates will set y to 0 and supply (7) strength has bigger value than weak (3) strength.
• If a = 0 and b = 1 then y will be 1 with pull strength because g1 will set y to 0 with weak (3) strength and g2 will set y to 1 with pull (5) strength (pull strength is stronger than the weak strength).
• If a = 1 and b = 0 then y will be 0 with supply strength because g1 will set y to 1 with strong (6) strength and g2 will set y to 0 with supply (7) strength (supply strength is stronger than the strong strength).
• If a = 1 and b = 1 then y will be 1 with strong strength because g1 will set y to 1 with strong (6) strength and g2 will set y to 1 with pull (5) strength.

2) The combination of signals identical in strength and value shall result in the same signal (If two drivers of a net have the same strength and value, then the net result will have the same value and strength)
Ex-2:
buf (strong1, weak0) g1 (y, a);
buf (strong1, weak0) g1 (y, b);
• If a = 0 and b = 0 then y will be 0 with weak strength.
• If a = 1 and b = 1 then y will be 1 with strong strength.

3) If two drivers of a net have the same strength but different values then signal value will be unknown and it will have the same strength as both drivers
Ex-3:
buf (strong1, weak0) g1 (y, a);
buf (weak1, strong0) g1 (y, b);
• If a = 1 and b = 0 then y will be x with strong strength.

Important Notes:
If one of the drivers has an H or L value, then the output value will be X.

Reference:
1) http://verilog.renerta.com/source/vrg00047.htm
2) System Verilog LRM (1800-2012)

Saturday, 30 April 2016

Override in UVM using factory with Example

One of the main advantage of UVM is Creating each components using factory enables them to be overridden in different tests or environments without changing underlying code base.

uvm_factory provides four different methods to override particular instance or all instances of particular class.
set_inst_override_by_type
set_inst_override_by_name
set_type_override_by_type
set_type_override_by_name


Let's go through example of each one of above four ways.

set_inst_override_by_type
-------------------------------------------------------

-------------------------------------------------------

-------------------------------------------------------

-------------------------------------------------------


set_inst_override_by_name

-------------------------------------------------------

-------------------------------------------------------

-------------------------------------------------------

-------------------------------------------------------


set_type_override_by_type
-------------------------------------------------------

-------------------------------------------------------

-------------------------------------------------------

-------------------------------------------------------


set_type_override_by_name
-------------------------------------------------------

-------------------------------------------------------

-------------------------------------------------------

-------------------------------------------------------

set_inst_override_* has high precedence than set_type_override_*.
i.e. If any particular instance of class is override by using set_inst_override_* and type of same class is overridden by using set_type_override_* then that particular instance of class is overridden by set_inst_override_* and rest other instances are overridden by set_type_override_*

-------------------------------------------------------

-------------------------------------------------------

-------------------------------------------------------

-------------------------------------------------------


UVM also support override through command line,
+uvm_set_inst_override=,,
+uvm_set_type_override=,[,]

work like the name based overrides in the factory--factory.set_inst_override_by_name() and factory.set_type_override_by_name().

Let's implement same example as above using command line arguments.
-------------------------------------------------------

-------------------------------------------------------

Simulation time argument:
+uvm_set_inst_override=A,A_override,uvm_test_top.env.a3 \
+uvm_set_inst_override=B,B_ovr,path1.b1 \
+uvm_set_type_override=A,A_ovr \
+uvm_set_type_override=B,B_override
-------------------------------------------------------

-------------------------------------------------------

Singleton class in System Verilog

Sometimes it is required to have only one object of some classes like configuration classes. For this purpose we create singleton classes.
Only one object is created for a singleton class and whenever we try to create a new object, same object is returned.

System verilog does not provide construct to create a singleton class. But we can create it with some manipulation.

---------------------------------------------------------------------

---------------------------------------------------------------------


uvm_root class defined as a singleton class in UVM source code.
---------------------------------------------------------------------

---------------------------------------------------------------------

Monday, 25 April 2016

UVM FAQ2


Why phasing is used? What are the different phases in uvm?
UVM Phases is used to control the behavior of simulation in a systematic way & execute in a sequential ordered to avoid race condition. This could also be done in system verilog but manually.


Which phases of UVM are Top-Down?
build_phase() & final_phase() are Top-Down, rest all phases are Bottom-Up.


Which phases of UVM are task?
run_phase(),
pre_reset_phase(), reset_phase(), post_reset_phase(),
pre_configure_phase(), configure_phase(), post_configure_phase(),
pre_main_phase(), main_phase(), post_main_phase(),
pre_shutdown_phase(), shutdown_phase(), post_shutdown_phase()


How do uvm phases initiate?
Calling run_test() constructs the UVM environment root component and then initiates the UVM phasing.


Why is the build_phase() in UVM executed in a Top - Down fashion and the other phases in Bottom - Up fashion?
The build phase has to be that way because the parent component's build_phase constructs the child components. You couldn't call the child's build_phase before the parent's build_phase because they the child objects haven't been constructed yet. You need a constructed object to call its method.
The build_phase() is also executed top-down so that the parent can provide override setting that the children will use when they execute their build_phase()
The ordering within the other phases should not matter, except you might want know that the top level's report_phase comes last.


What is the order of execution of run_phase() ?
The run_phase() of each component is executed concurrently with no defined order you can depend on.


During the run_phase() is there something like super.run_phase(phase) called?
You only need to call super.method() if you are extending a class an need the functionality of the base method. There is nothing inside the run_phase() of a uvm_component, so there is no need to call super.run_phase() when extending from it.
You may want to call it when extending your classes from your base classes.


What is the difference between run_phase and main_phase in uvm_component?
Actually, you can start a sequence in any phase. It is more important to understand the domain/scheduling relationships between the task based (i.e. runtime) phases.
UVM undergoes a number of pre-simulation phases (build, connect, end_of_elaboration, start_of_simulation) that are all implemented with functions. Once those are completed, the task based phases begin.
The standard includes two schedules.

  • One is simply the run_phase, which starts executing at time zero and continues until all components have dropped their objections within the run_phase.
  • The other schedule contains twelve phases that execute parallel to the run phase. They are: pre_reset, reset, post_reset, pre_config, config, post_config, pre_main, main, post_main, pre_shutdown, shutdown, and post_shutdown. They execute in sequence.

Every component has the opportunity to define or not define tasks to execute these phases. A phase starts only when all components in the previous phase have dropped their objections. A phase continues to execute until all components have dropped their objections in the current phase.


Why connect_phase() is bottom-up?